As AI adoption accelerates, enterprises are increasingly focused on the cost and efficiency of running models in production. Delivering high-throughput, low-latency inference while managing power consumption and infrastructure costs has become a critical challenge.
Oracle Cloud Infrastructure (OCI) is expanding its AI compute portfolio with Positron Atlas, a purpose-built inference platform designed to deliver efficient, scalable inference for transformer-based workloads.
By combining Positron’s memory-efficient accelerator architecture with OCI’s high-performance infrastructure and Oracle Acceleron networking, customers gain another option for optimizing AI inference performance and cost.
Positron Atlas Inference Servers are purpose-built for Large Language Models, delivering real-time, low-latency performance for popular open weight models. Positron Atlas is networked through Oracle Acceleron, OCI’s suite of network software and architecture designed to remove networking bottlenecks for scaled inference applications, to increase performance, enhance security, and simplify operations.
Purpose-Built for Transformer Inference
Positron Atlas is purpose built for transformer architectures, which power today’s popular LLMs. Positron Atlas uses a custom accelerator architecture optimized for LLM inference. Memory bandwidth is one of the primary bottlenecks in transformer workloads. With benchmarked memory-bandwidth efficiency of 93%, Positron accelerators offer a 3–5× TCO advantage for targeted workloads, due to power efficient accelerators and fast request completion times.
This makes Positron Atlas on OCI well-suited for:
- Cost-efficient deployment of smaller workhorse models like GPT-OSS, Qwen 3.5 and Gemma 4
- Real-time AI agents, assistants and coding copilot tasks
- Hot-model hosting and dynamic model switching with zero loading overhead
- High-throughput continuous-demand inference APIs
Rapid Deployment
Software migration and adoption is seamless with OpenAI-compatible APIs. Teams can run existing models and integrate with popular open-source LLM models—accelerating time to production while minimizing engineering effort.
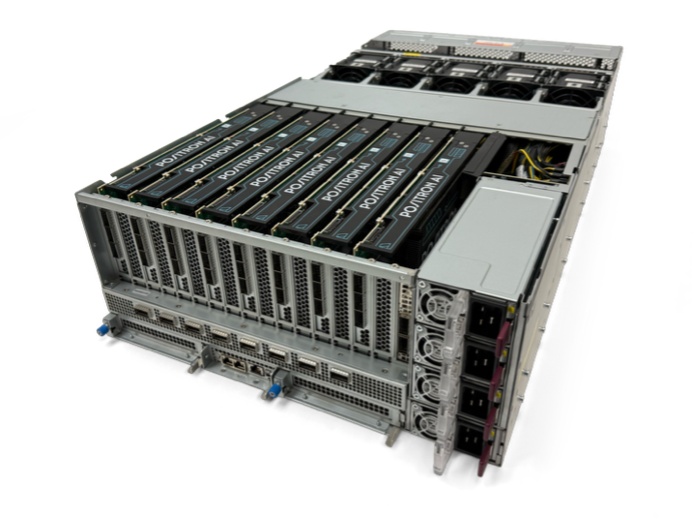
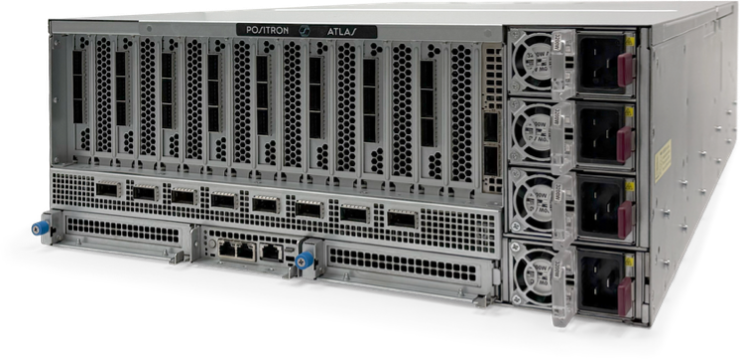
Positron Atlas Instances on OCI
OCI Infrastructure, Oracle Acceleron, and Positron Atlas systems are designed to deliver strong performance and efficiency for production AI workloads, combining purpose-built accelerators with high-performance compute and networking:
- 8× Positron AI accelerators for high-throughput inference
- Tightly coupled high-performance memory for up to 500B model weights
- OCI Acceleron hardware-level security isolation
- 144-cores Intel Xeon 6 CPU (up to 4.4 GHz turbo)
- 1.5 TB system memory to support large model and data pipelines
- 30 TB of local NVMe storage for fast data access
- 200 Gbps networking for high-throughput communication
Get Started with OCI Compute and Positron Atlas
With the addition of Positron Atlas, OCI continues to broaden its AI infrastructure portfolio to give customers more flexibility, choice, and control. Whether leveraging general-purpose GPUs or purpose-built accelerators, customers can select the right platform for each workload—enabling more efficient, scalable, and cost-effective AI deployments. Positron Atlas Instances on OCI are available now – get started by reaching out to your OCI Sales Representative or by contacting Sales at Positron AI today.
About Positron AI
Positron AI builds hardware and software to make AI inference dramatically cheaper and more energy efficient. The company’s shipping product, Atlas, is deployed at hyperscaler scale today, and its next-generation custom silicon, Asimov, tapes out in late 2026 with production in the second half of 2027. Asimov powers Titan, a multi-terabyte-memory inference system for long-context and next-generation AI workloads. Positron’s energy-efficient architecture allows its systems to be deployed in air-cooled or liquid-cooled data centers at varying rack densities, without dependence on constrained HBM or CoWoS supply chains. Learn more at positron.ai.